Deploy AI Models. NotInfrastructure.
Move from Model Development to Production AI.
Deploy and serve trained AI models through inference infrastructure designed to support application performance, secure connectivity, and changing compute requirements. Invincible Inference as a Service helps enterprises and developers bring language models, computer vision systems, and intelligent applications closer to production through scalable GPU computing and API-based deployment options.
Everything You Need to Put AI Models to Work.
Explore the infrastructure capabilities required to connect trained AI models with enterprise applications and production workloads.
Scalable Inference Endpoints
Expose supported AI models through inference endpoints designed to handle application requests and evolving traffic.
Secure VPC Networking
Explore Virtual Private Cloud networking options for controlled communication between inference services and enterprise applications.
Private Model Hosting
Evaluate isolated or dedicated infrastructure options for workloads requiring greater deployment control.
API-Based Model Access
Integrate supported AI model inference capabilities with external applications and developer workflows.
Load Balancing & Traffic Management
Distribute application requests across suitable infrastructure configurations to support workload management.
Monitoring & Performance Visibility
Review supported inference metrics and operational information to understand application performance.
Dedicated GPU Inference
Explore GPU infrastructure configurations designed for compute-intensive AI inference workloads.
From Trained Models to Intelligent Applications.
Connect AI models to applications through a structured deployment and inference workflow.
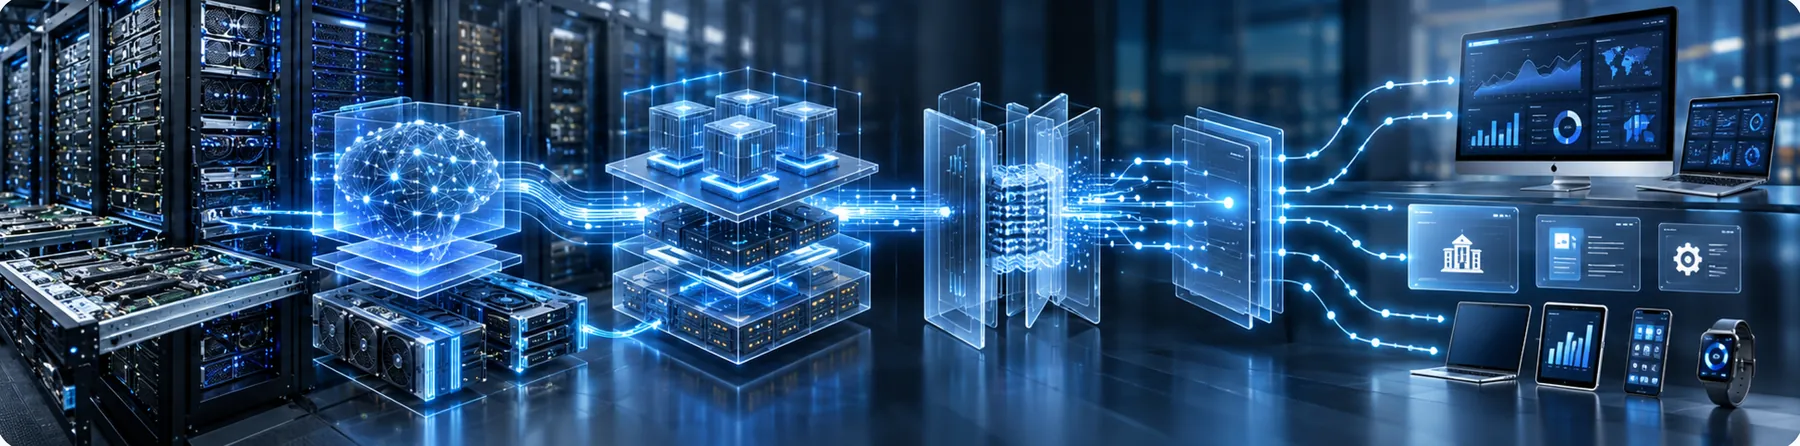
Stage 1 — Model
Select a supported trained model or evaluate private deployment requirements.
Stage 2 — Infrastructure
Choose appropriate GPU computing, networking, and deployment resources.
Stage 3 — API Endpoint
Expose model capabilities through a supported inference interface.
Stage 4 — Application
Integrate the inference endpoint into enterprise systems and intelligent applications.
Bring AI Intelligence Into Real-World Applications.
Enterprise AI Assistants
Support conversational AI, internal knowledge assistants, and information retrieval applications.
Document Intelligence
Process and interpret documents for extraction, search, and automated workflows.
Computer Vision Applications
Run model inference for images, object recognition, and video analysis.
Intelligent Business Automation
Integrate AI model capabilities into enterprise applications and business workflows.
Focus on Your Application. Simplify Your Infrastructure.
Inference infrastructure brings together model hosting, computing resources, APIs, and application connectivity, helping teams focus on delivering useful AI capabilities.
Reduced Infrastructure Complexity
Explore managed or configured inference resources instead of assembling every infrastructure component independently.
Deployment Flexibility
Evaluate shared, dedicated, or private deployment options according to application requirements.
Integration-Ready AI
Connect supported inference services to business systems and development workflows.
Your Models Are Ready. Put Them to Work.
Explore deployment options for AI models and connect inference capabilities to your applications.